In 2026, we’ve rebuilt Jsonify from the ground up. No more workflow builders – ours included. RIP.
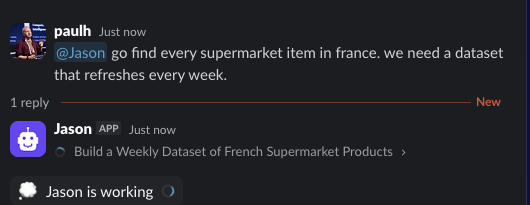
Instead, we’ve hired Jason, our latest employee, as the Head of Data. Working with him is simple: tell Jason what data you need. Like this.
Behind the scenes, Jason is an AI agent with his own desktop, browser and smartphone. He researches, writes and runs code, tests hypotheses, and builds data pipelines. He’s armed with the best web scraping, document parsing and mobile engineering toolkit possible – built on the same best-in-class web extraction and browser agent platforms powering large enterprises and startups alike at Jsonify since 2023.
Jason’s job is to figure out where the data you need lives, and how to get it for you, reliably and repeatedly.
Most structured-data extraction tools – us included, in 2024 – point an LLM at a page and ask it to turn the mess into rows. That works great, to start! But it also costs a fortune at scale, and gives you slightly different rows each time, which is a nightmare to reconcile over time. Ask me how I know.
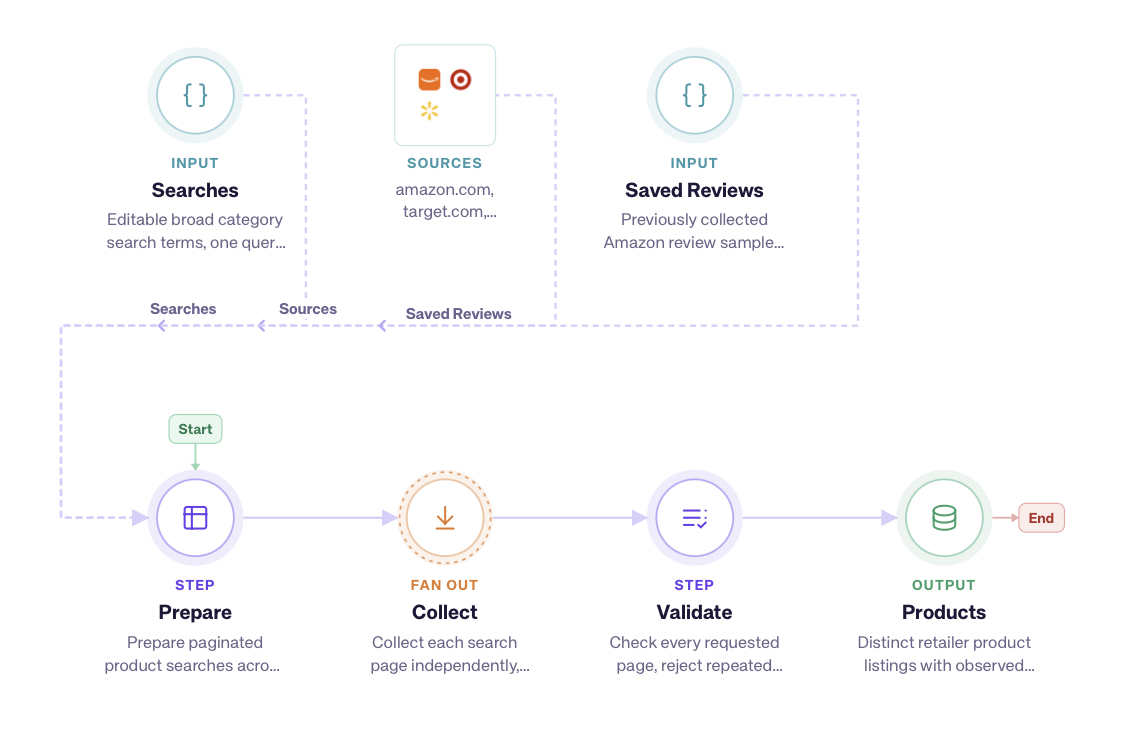
Not any more. Jason is a data engineer, not a data extractor. He writes and maintains a deterministic pipeline: real code, run over and over on our cloud (or on-prem for enterprise), producing the same rows the same way each time.
The AI builds the pipeline. The pipeline gets the data.
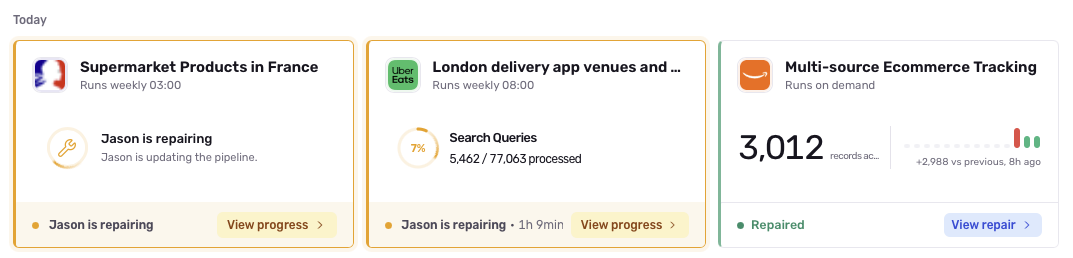
Of course, the web changes constantly. Pages move, apps update, documents disappear. When a pipeline inevitably breaks, Jason gets paged. He inspects it, fixes it, and gets your data flowing again.
You find out when it’s done, if you care to know. You probably won’t.
So you don’t do anything except sit back and get the data delivered.
As it should be – you’ve got a business to run. You shouldn’t have to care about how scraping tools or proxies or browser agents or parsers get configured, or how best to assemble and maintain the fragile stack of brittle-but-powerful tooling that modern data engineering is built on. In 2026, humans should be spending their time on more interesting things.
So that’s Jason’s problem now, not yours. He has one job, so you can get back to yours.
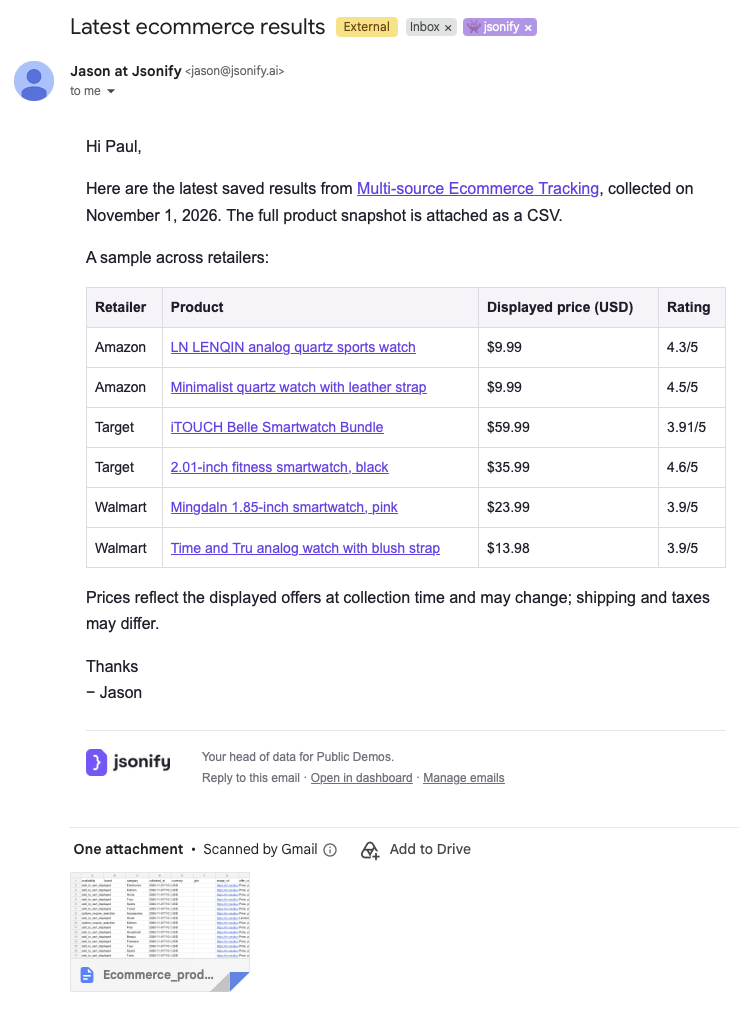
Output lands where your tools already are: Google Sheets, Excel, Snowflake, S3, or straight into ChatGPT, Claude or Copilot through our plugins, so your AI tools can do the dashboards and the analysis.
We get you the data. What you do with it is yours.
We built Jason internally to keep enterprise pipelines running for customers like Bacardi – “price every cocktail on every bar menu in Europe every week make no mistakes” is the kind of millions-of-sources job that forced us to get serious about maintaining and scaling data engineering.
Then we noticed the same thing works at every scale. A founder who needs 500 rows has the same problem as Bacardi, minus the zeros.
So Jason now works for everyone. 100 rows a month free, no card. After that you pay per row of QA-passed, useful, reliable data delivered – not credits, not API calls, not seats. Rows.
We’ve been piloting the new Jsonify for a few months now with startups and large enterprises, and it’s been super fun to see the kinds of data people are collecting and maintaining with it. A few public examples, with some sample rows:
Sample data is free! Or fork the pipeline from the page above, modify it, and collect your own dataset.
Got some ideas? Tell Jason what data you need, on jsonify.com or email him directly: jason@jsonify.ai.
Or drop requests in the comments on LinkedIn, I’ll pass it on!
-paulh